Scar of Quantization
I want to share a common failure pattern of quantization aware training: quantization can leave scars in tensor.
I found this while investigating an INT8 pretraining run where training loss kept falling but validation loss did not converge. Outliers were causing smaller activations sharing their scale to round to zero, leaving visible scars. The interesting part was watching them change during training: some healed, while others stayed until the end.
Below is one of the problematic activation tensors: the activation of (mlp.down_proj), captured for the same sequence across different training checkpoints. The pale bands show activations rounded to zero. One band faded, but another was still there at 50k steps.
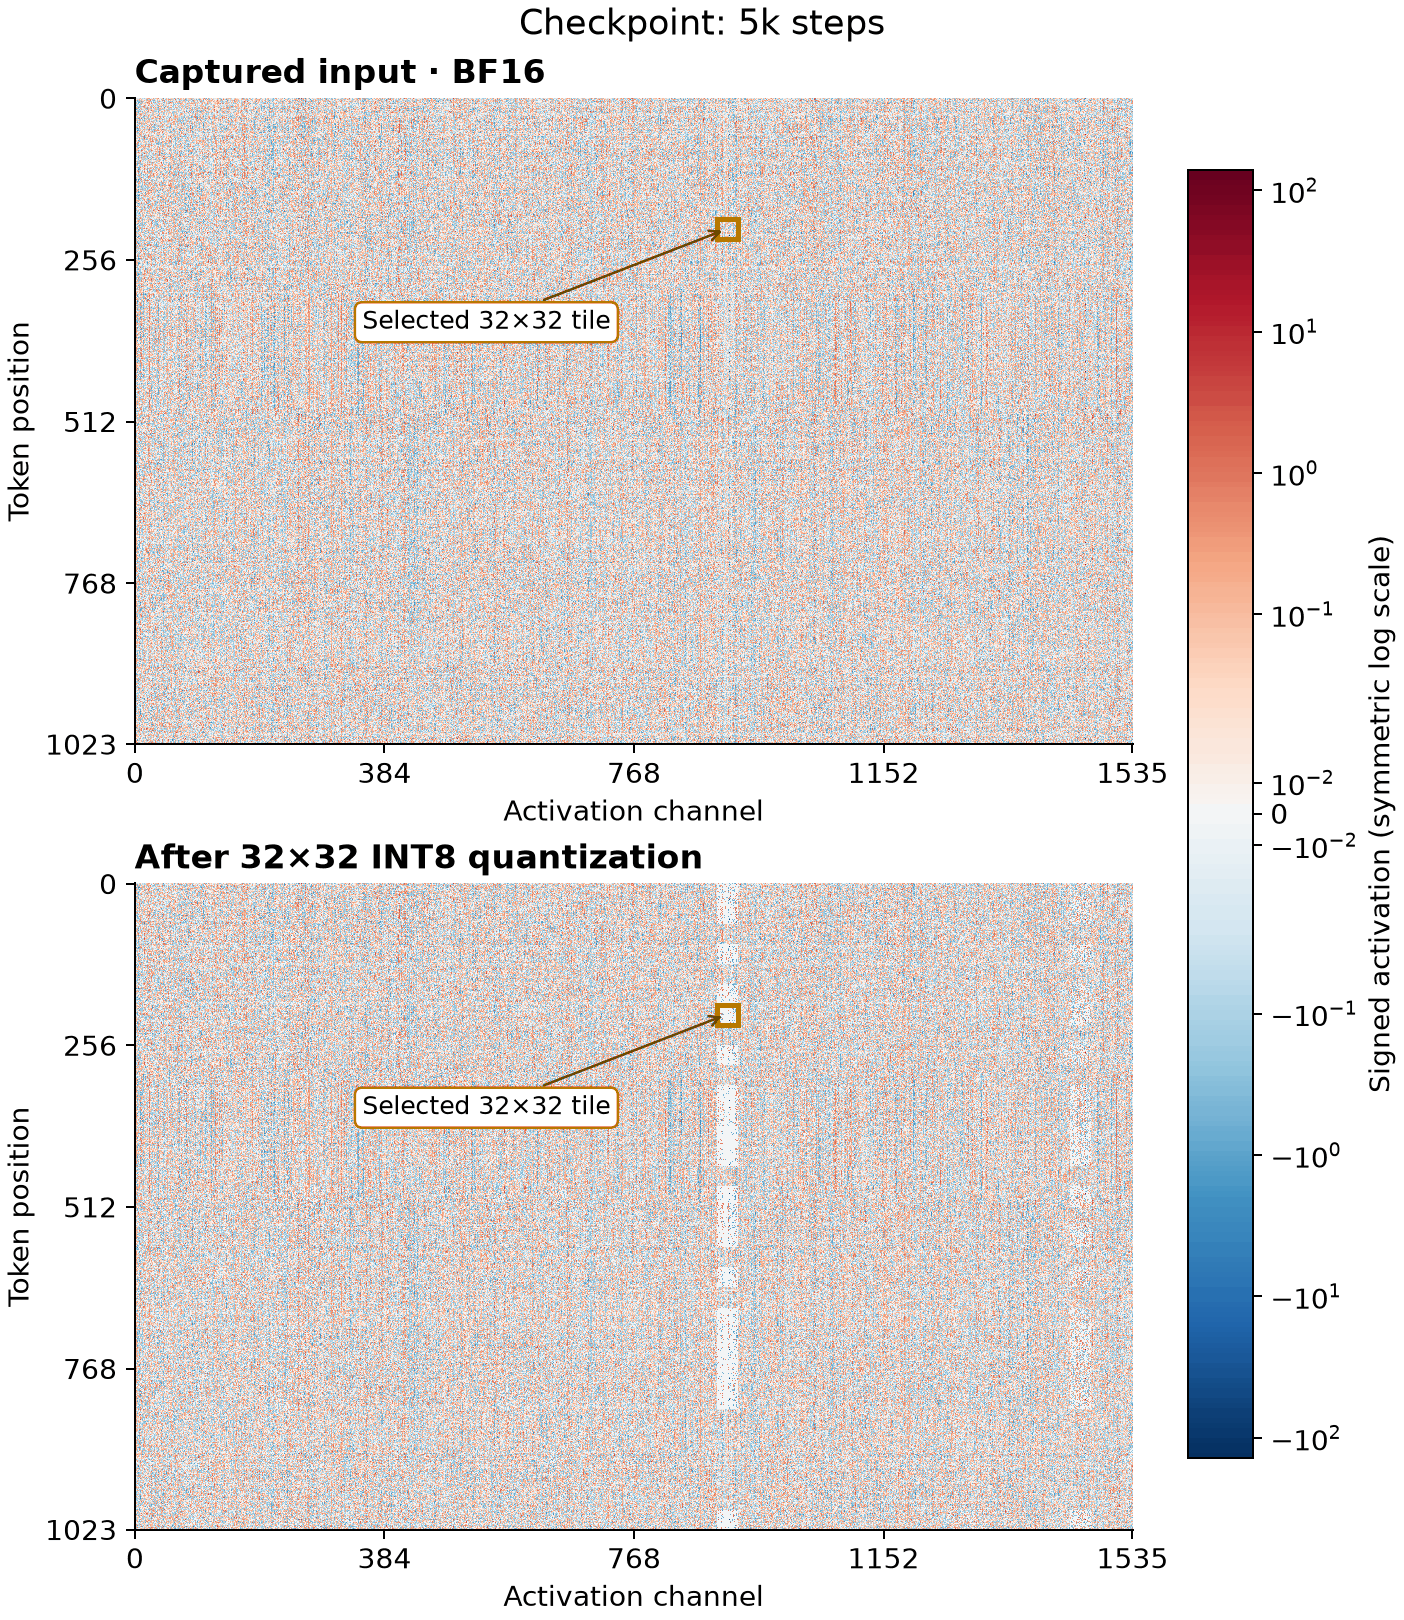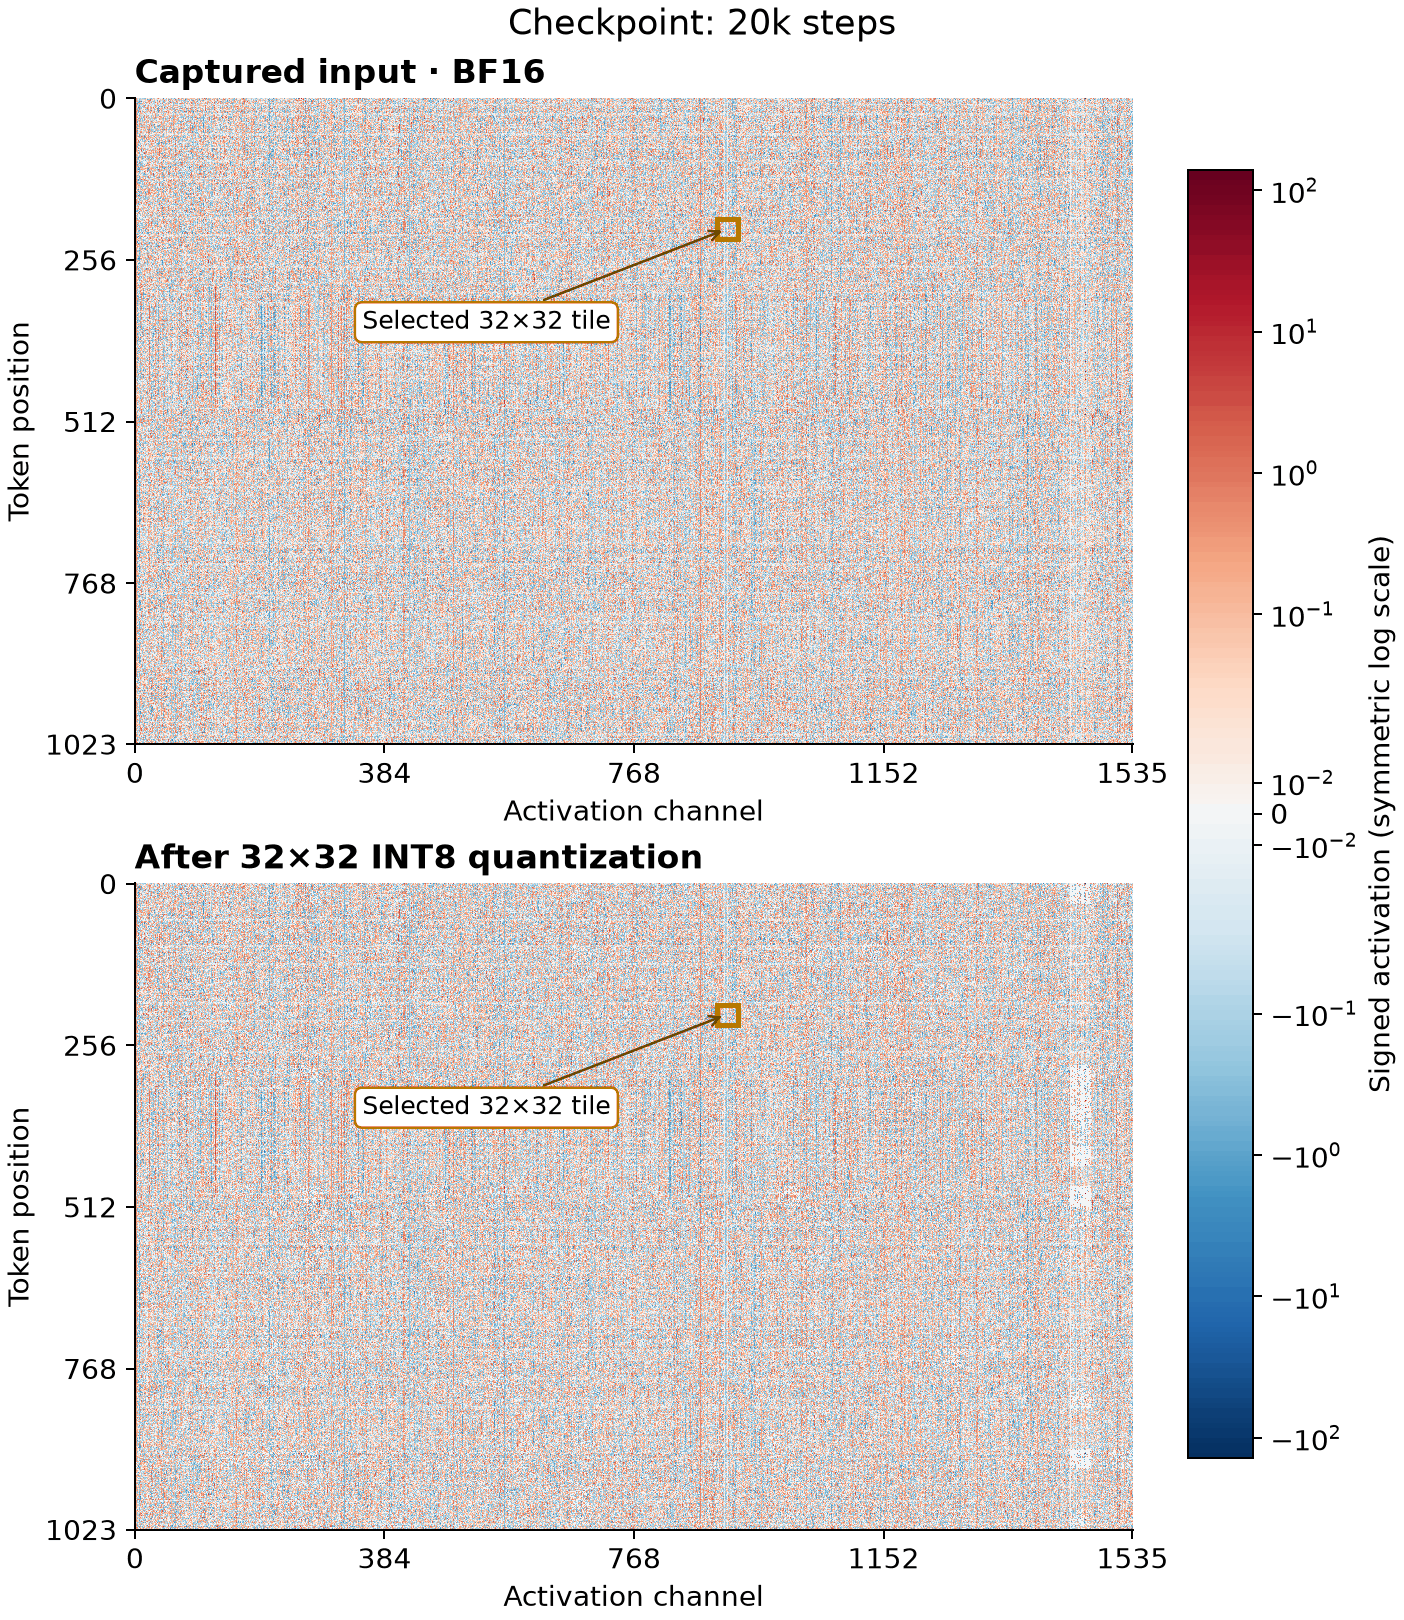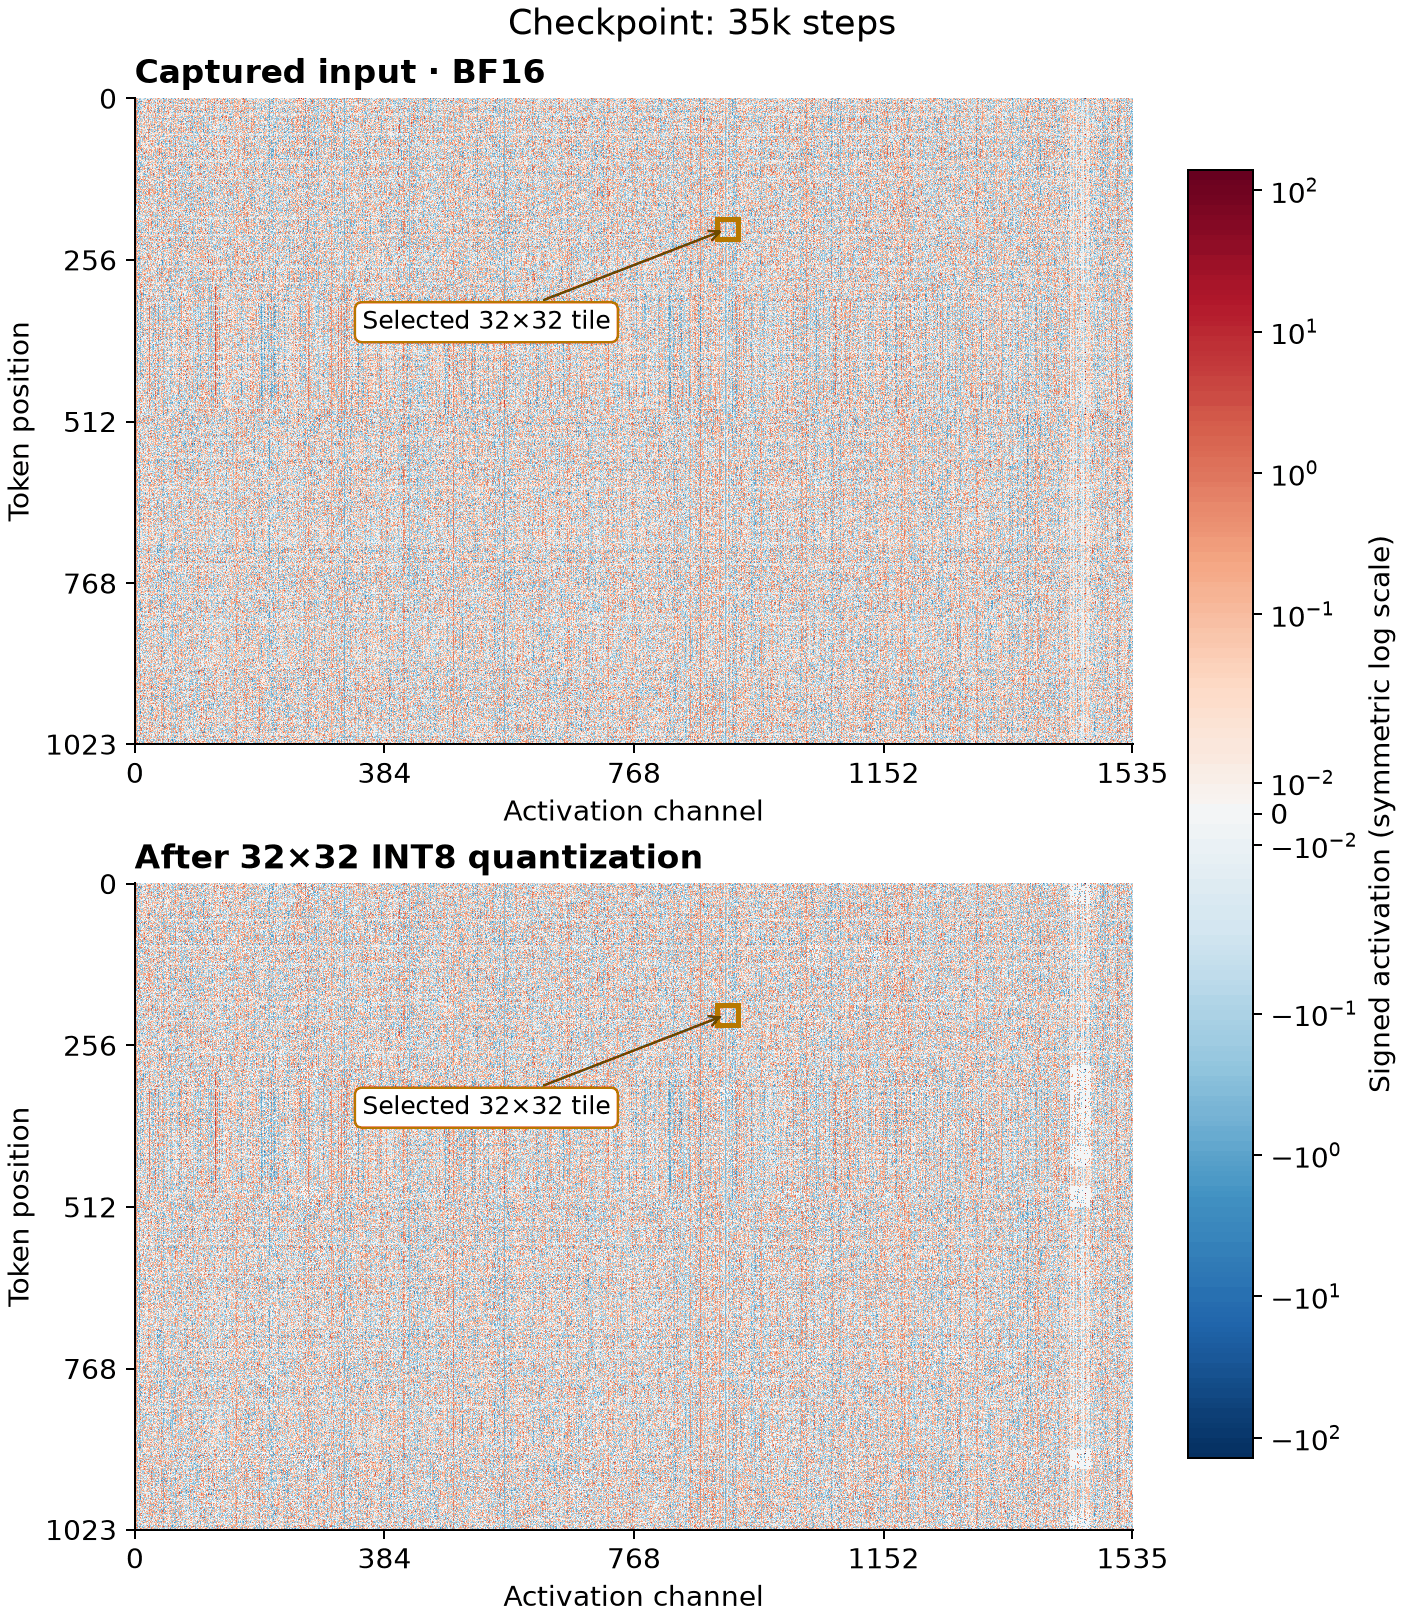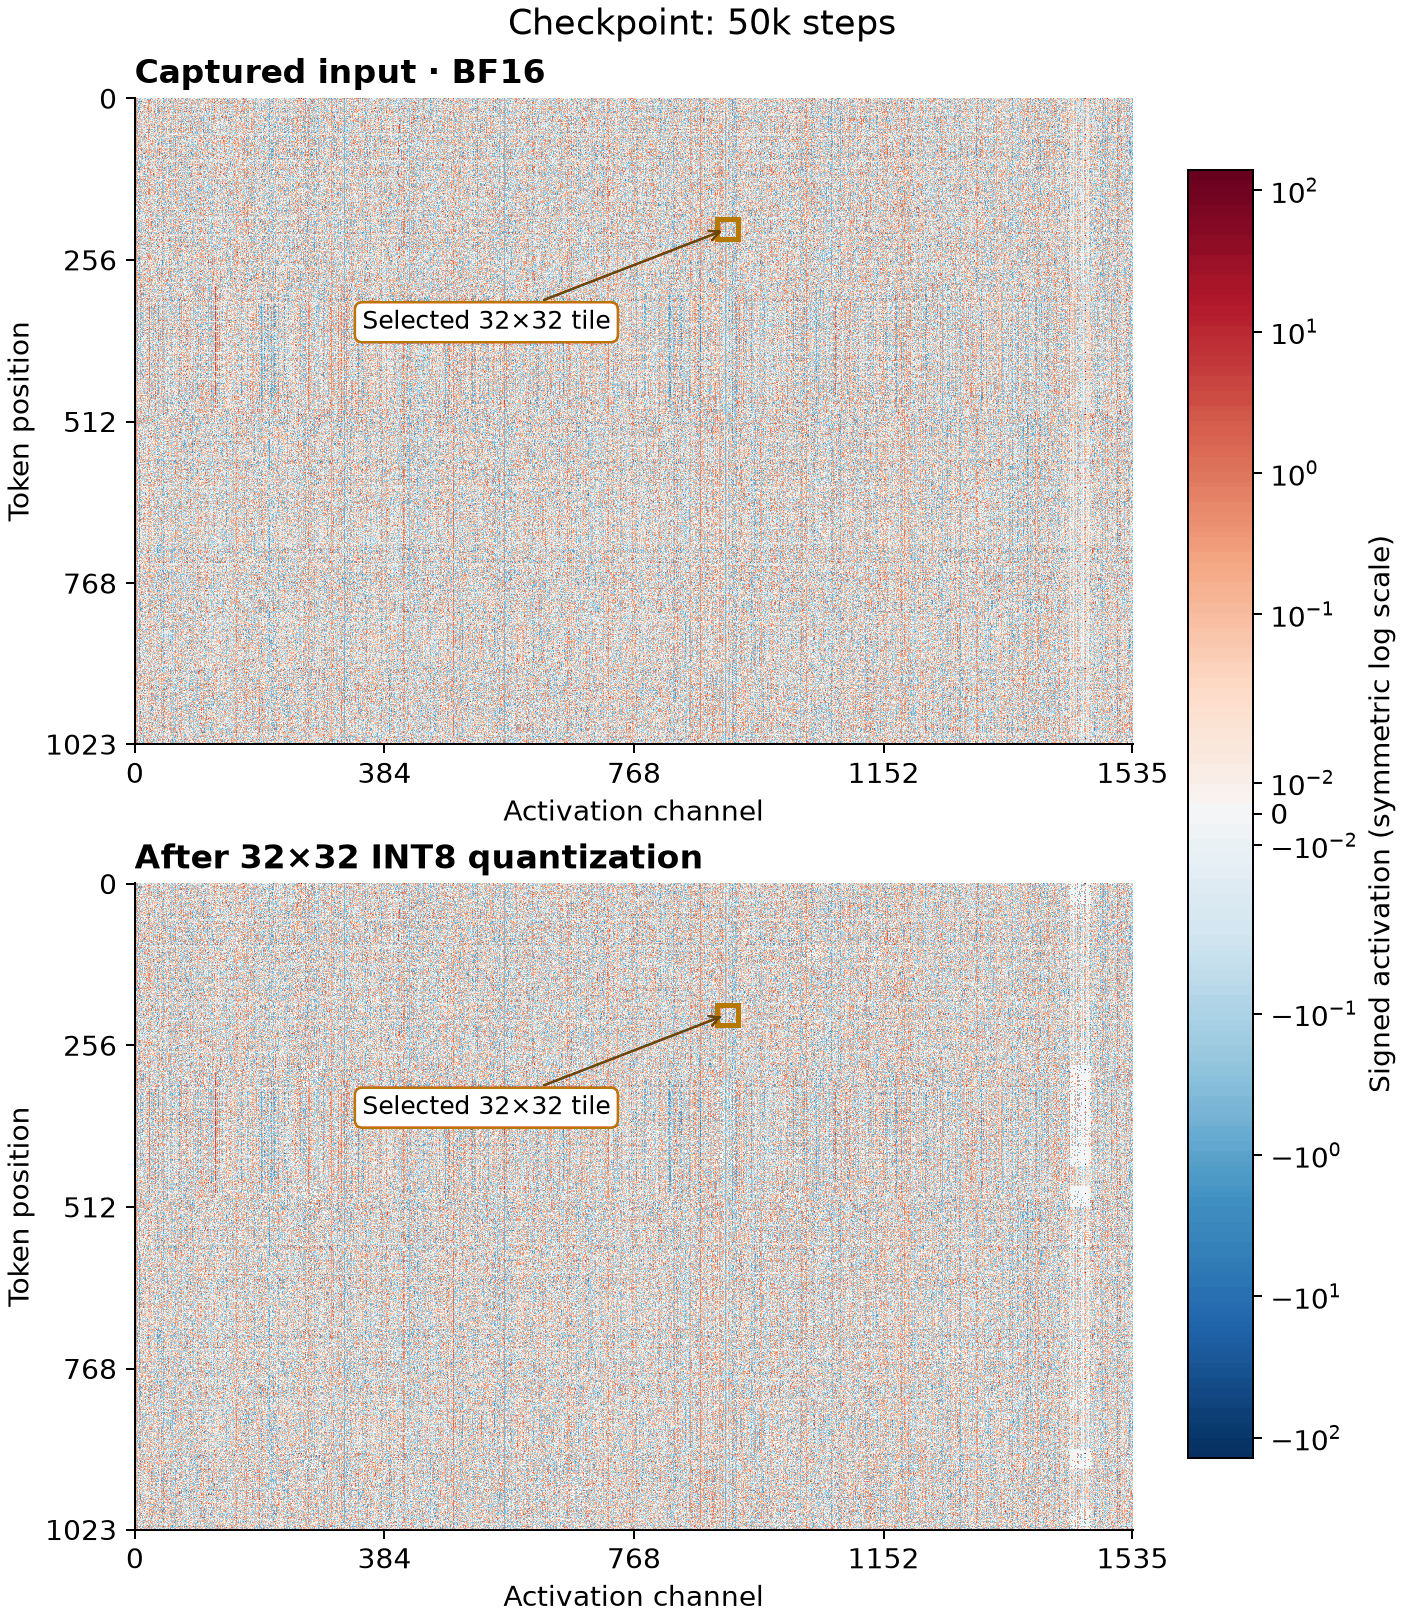
Same sequence’s activation across checkpoints; lower panel: dequantized activations. Colors use a fixed symmetric logarithmic scale.
The problem with 2D blocks is how far one outlier reaches. A single scale covers 32 tokens and 32 channels, so a large activation can erase smaller values across the whole tile. In the example below, a −140 outlier leaves about 92% of the tile rounded to zero. With 1×32 scaling, that falls to about 9%.
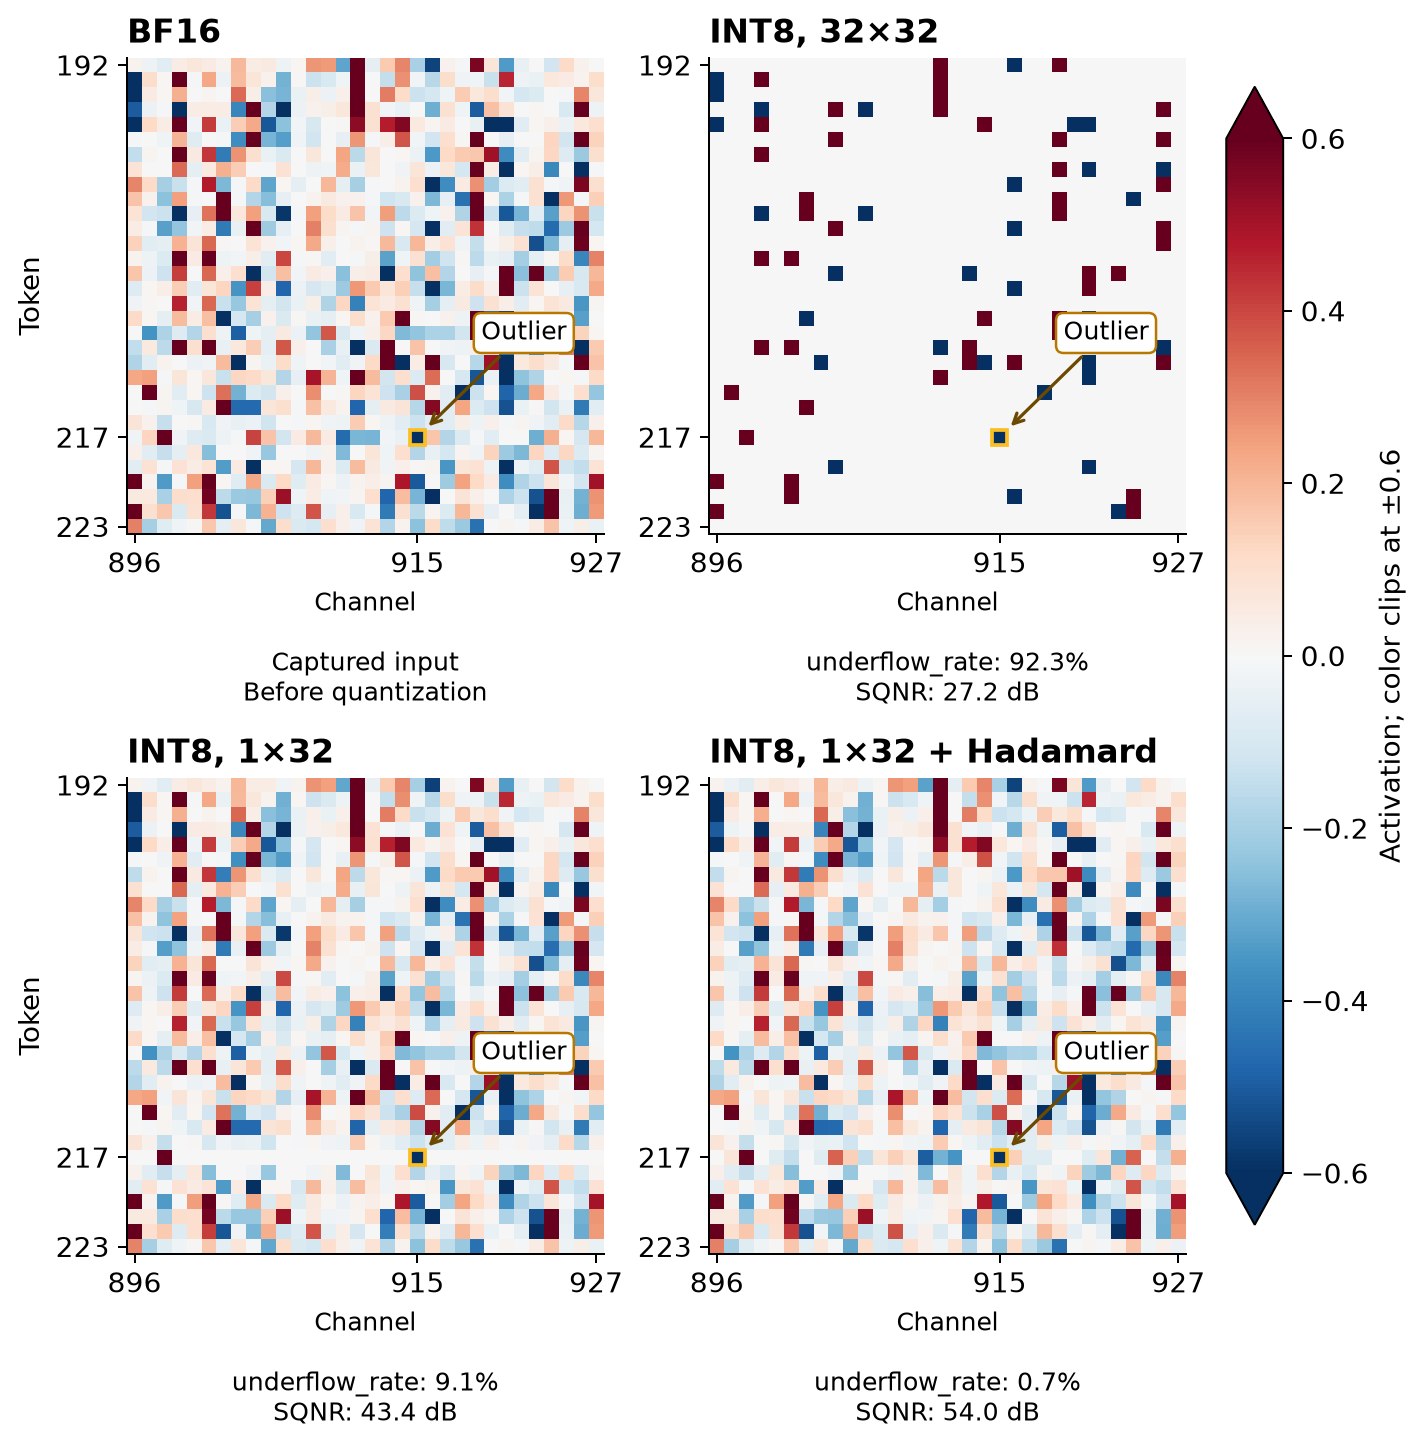
Same 10k input; colors clip at ±0.6. Orange boxes mark the outlier. Hadamard is tested offline and shown after inverse rotation. underflow_rate is the fraction of nonzero inputs rounded to zero, measured before inverse rotation.
Both schemes preserve the outlier. With 1D blocks, its effect stays within one token’s 32-channel group in the forward pass. The scar is smaller, but it still exists and can disrupt training.
I retrained with 1×32 quantized activations, keeping weight quantization unchanged. The losses converged this time.
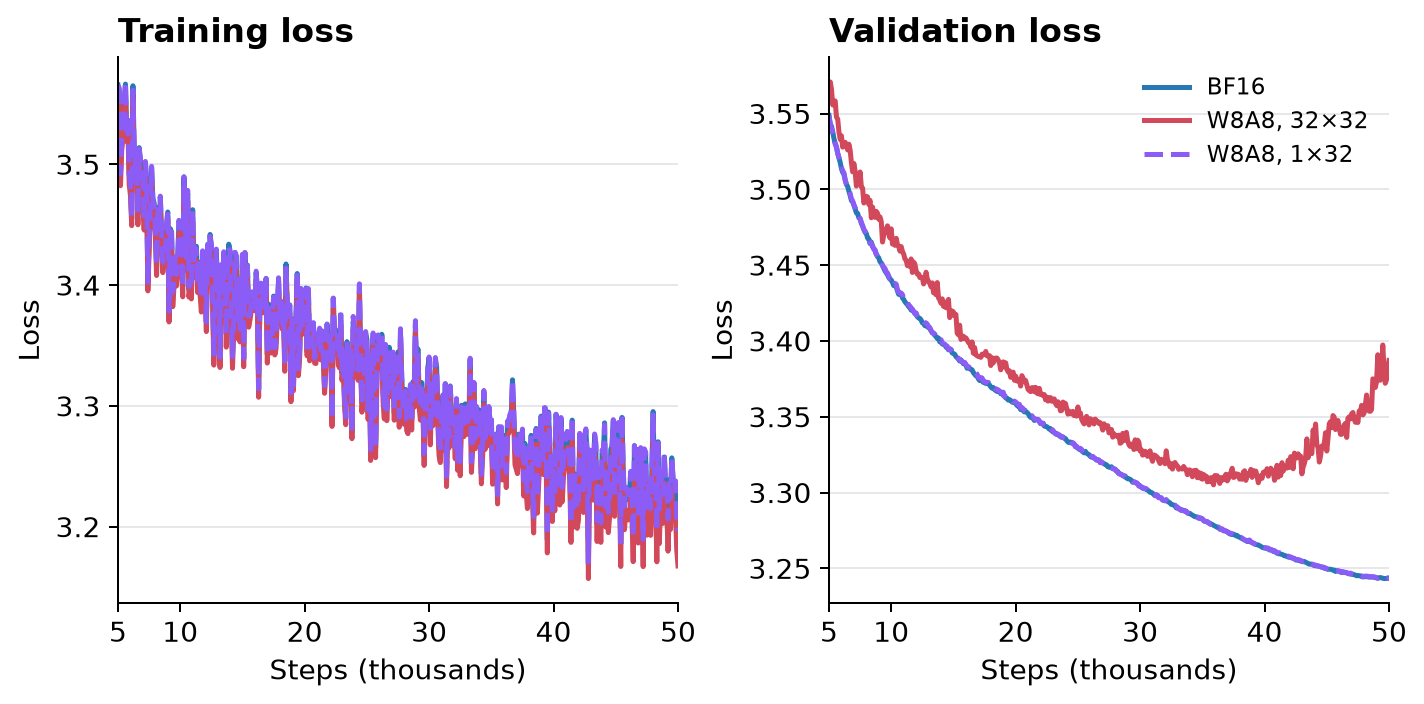
Validation uses BF16 with quantization disabled.
When scaling up the model size, 1D may not be enough. Outliers can hurt neighboring features sharing the scale, as the LLM.int8() observations illustrate for vector-wise quantization. If that still breaks training, I’d consider Hadamard rotation to spread outliers before quantization. It improves this tile’s signal-to-quantization-noise ratio from 43.4 to 54.0 dB, though I haven’t trained with it here. NVIDIA’s NVFP4 training recipe uses random Hadamard transforms for weight-gradient operands.
Another case to watch out for is attention: sharing quantization scales across tokens can leak future information, even with a causal mask, as MatX shows.
References
- INT8 pretraining experiment recipe
- Tim Dettmers: LLM.int8() and Emergent Features
- NVIDIA: NVFP4 training and random Hadamard transforms
- MatX: Future leakage in block-quantized attention